A language for AI applicationsExperiments with XJSN and domain-specific languages.
Building Idyllic - Prior Iterations
September-October 2025
A delivery route contains stops, constraints and decisions about their order. A programmer can represent those concepts in code and ask a coding assistant to change them. Someone who understands the delivery business should be able to make the same kinds of changes without first building the database, API and screens around the route.
The earlier Idyllic builders let me assemble prompts, procedures and tools. I now wanted to give the agent a representation of the activity itself, with objects it could inspect and operations whose meaning was already defined.
Giving the domain a vocabulary
I called this work domain encoding. For a routing application, the vocabulary would describe the things the business cared about and the valid ways to work with them. An operation might still make database calls underneath, but the person and the agent would encounter the domain concept those calls served.
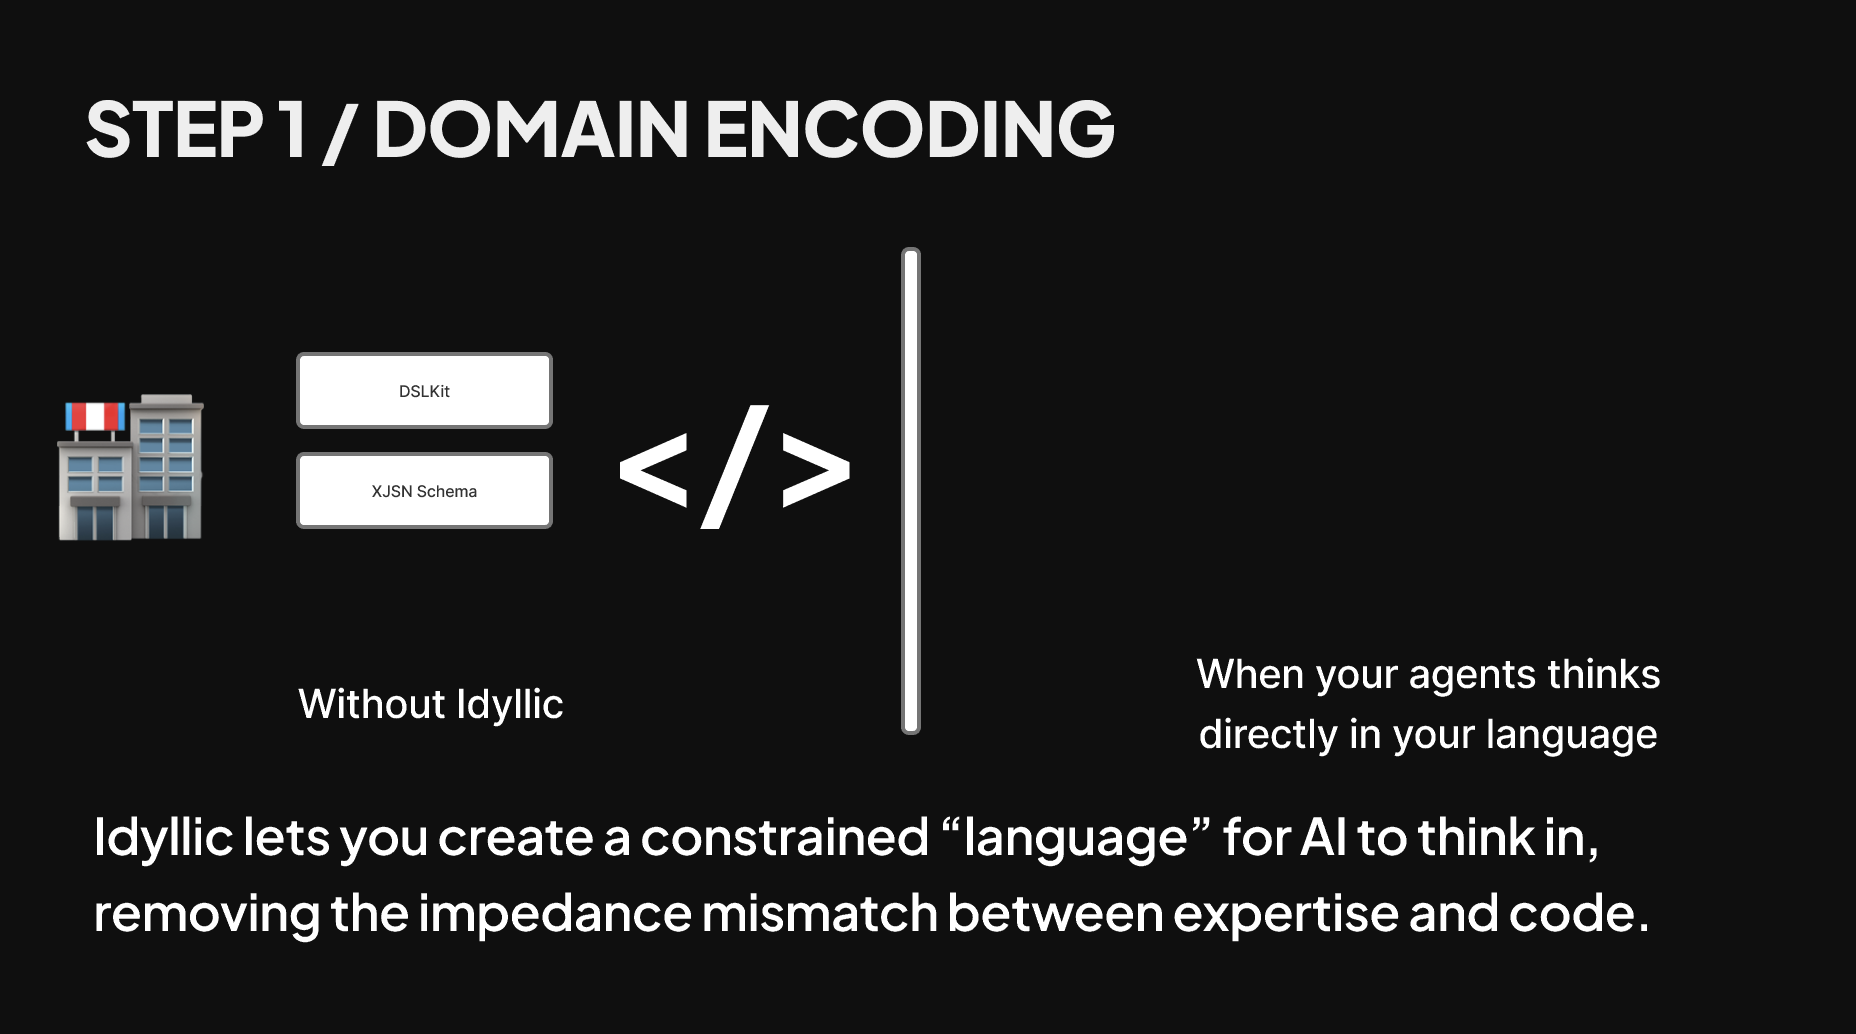
The proposal slide places DSLKit and XJSN Schema between the business and its representation as code. Idyllic would supply the language machinery. Each application would supply the concepts and rules that made its language useful.
A domain-specific language has a deliberately limited job. If the agent is planning routes, it needs to express route-related work. It does not need permission to invent arbitrary database operations or modify the application implementing those routes. The available vocabulary can keep the generated program within a space the application knows how to interpret.
Choosing that vocabulary is substantive design work. Exposing every low-level database operation would leave the model to reconstruct the business's rules each time. A useful domain operation can carry some of those rules in its implementation, so the model selects and combines meaningful actions. The language's expressive power comes partly from what has already been decided inside those actions.
Letting the model write a program the system can check
I had been implementing and testing XJSN, short for Extensible JavaScript Notation, as a common notation for these languages. It combined JSON values with function-call syntax. Models were already familiar with that shape from code, and a person could read a nested call without working through a stack of tagged JSON objects.
The calls were inert. Parsing an XJSN expression produced a tree of data; it did not execute JavaScript. The application could inspect that tree before allowing any operation to run.
The parser and schema had different jobs. The parser recovered the expression's structure: a call with a name, arguments, and perhaps other calls nested inside those arguments. The schema specified which names existed and what arguments they accepted. The same parser could therefore serve a routing application or a customer-management application, while each schema exposed a different language.
A generated expression passed through a sequence of checks:
- The model received the domain's available operations and wrote an expression.
- The parser converted that text into a structured tree.
- Validation checked the calls and their arguments against the domain schema.
- If validation failed, an error could identify the offending call and the expected argument, giving the model something specific to repair.
- An interpreter could carry out the checked expression through the registered operations.
The distinction matters when a generated call is almost right. A call can have perfectly valid syntax while referring to an unknown operation or supplying text where a number is required. Parsing alone cannot catch that mistake. A schema can describe it precisely enough that the next attempt repairs the argument instead of blindly regenerating the whole program.
The schema also supplied the information used to instruct the model. That kept the description of the available language tied to the definitions used by its validator. Adding an operation would otherwise require maintaining separate accounts of what the model was told and what the system accepted. I describe this generation and repair loop in more detail in the XJSN article.
My experiments encouraged the hypothesis that limiting what the model could express would help it perform a particular job reliably. The next problem was deciding whether a valid expression did useful work.
Designing behavior within the language
A route can contain valid stops in an allowed order and still be a poor plan. The language establishes what the system can understand. Choosing an appropriate route also depends on the information the agent receives and the decisions it makes with that information.
I called this second stage intelligence design. It included the context, examples and procedures that guided the agent's behavior. An application author would define how the agent approached the work, while the domain language gave that behavior definite objects to act on.
The separation made failures easier to locate. An unknown function belongs to the language's validation problem. A valid but unhelpful plan points toward the agent's instructions, missing context or decision procedure. Improving one does not automatically improve the other.
This was the property I wanted to carry over from coding environments. A coding assistant can inspect an artifact, change part of it, and receive feedback at a specific location. I wanted work with routes and business procedures to have an equally inspectable representation, so an agent could revise the work instead of only discussing it.
Making the representation visible
I also wanted to operate the encoded system through a board of widgets. Each widget would hold useful state, make that information available to the agent, and update when the agent changed it. Once configured, the same system could be used through the interface or an API. This was the product design we were developing, with the integration path still open.
An equipment-support example helped us work through what the interface should contribute. Before starting a conversation, a restaurant operator could select the piece of equipment they needed help with. That selection would supply information the application already knew, instead of making the operator reconstruct it in a prompt. The assistant could then begin with the selected equipment and ask about the problem.
The example exposed decisions that a language alone could not settle. We still needed to establish where the equipment data came from, what the operator saw, and what belonged in the administrator's view. We discussed rough wireframes to make those choices concrete enough to get feedback on.
I wanted the interface for my own testing too. If an agent changed a domain object, I needed to see the change and understand what it had done. The widget board would connect the language experiment to an observable result: a person supplies context, the agent acts on the relevant object, and the updated object appears in the application.